Hyperion Financial Management and Azure Databricks
Oracle’s Hyperion Financial Management (HFM) is a cornerstone for global financial reporting. It enables consolidation between entities of the company while maintaining a regulatory filing to General Ledger (GL) audit trail [1]. Within insurance agencies, these statements are vital for reserve building, price structuring, and strategic decision-making.
Previously, extracting this data for reporting was a manual, repetitive task prone to human error. Synvert’s goal was to automate this transfer from HFM to Azure Databricks, transforming a bottleneck into a streamlined, scalable data pipeline.
Understanding the HFM Data Landscape
HFM data is multidimensional. For example, a single entry might represent a posting on an account, for a legal entity at the start of a period. This example shows only a few of the available dimensions within HFM. The dimensions – such as entities and accounts – are organized into hierarchies:
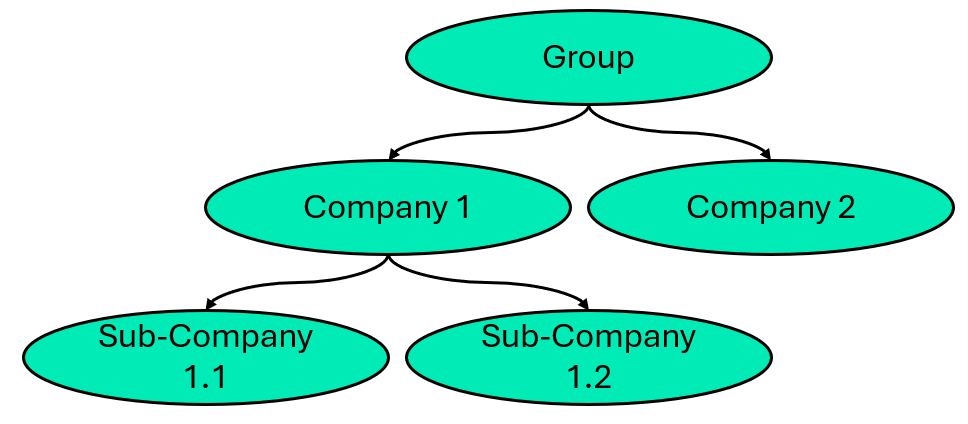
Level 2: Regional Companies (e.g., EMEA, Americas)
Level 3 (Leaves): Specific market-level sub-entities.
Unlike some systems, HFM allows entries at both the leaf level and at parent nodes (e.g., group-level adjustments). Capturing this nuance is critical for accurate reporting.
The problems of the past and future benefits
There are several use cases for exporting HFM data into Azure Databricks, such as the automation of calculations and reporting. This is especially relevant for standardizing reports, for example by migrating from Microsoft Excel exports to dedicated reporting software like Microsoft Power BI for comprehensive visualizations and analyses.
Previously, extractions from Hyperion Financial Management were done either with the help of Microsoft Excel extensions or directly in Hyperion Financial Management. Exporting data from within Hyperion Financial Management requires the manual selection of the scope for each dimension. This creates a monotonous, repetitive task that is prone to human error.
Both procedures require users to be set up in Hyperion Financial Management. These users need permissions and governance for their access. Within Azure Databricks or Microsoft Power BI, one can rely on a centralized identity provider like Microsoft Entra ID. This ensures consistent governance of user accounts across systems within the organization.
The Path to Automation: MerlinXL and API Integration
HFM does not offer a native “out-of-the-box” connector to Azure Databricks. To bridge this gap, we utilized MerlinXL by Amosca. [2]. The MerlinXL connector provides an API interface, where we define the type and scope of the data to be extracted and receive the requested data on the Databricks cluster.
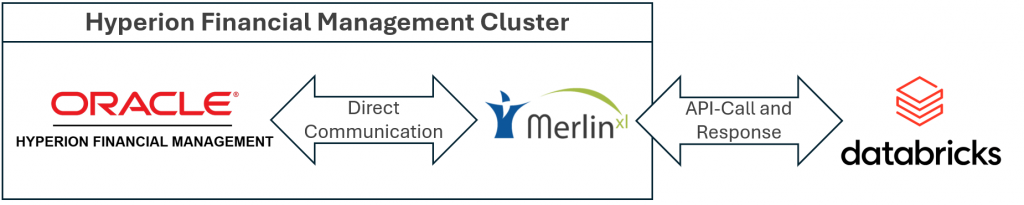
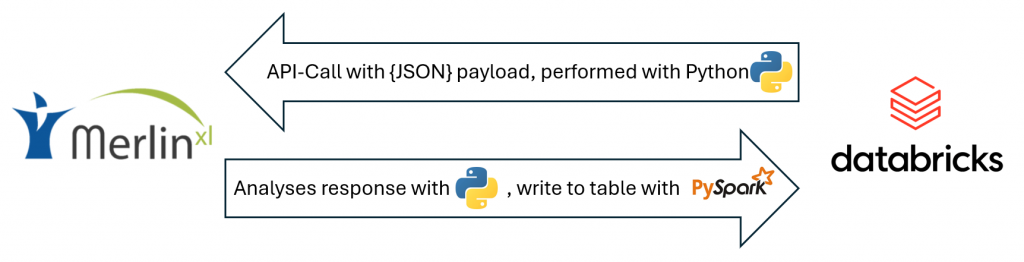
The MerlinXL connector accepts configurations as payloads in JSON format. In short, this enables us to configure a multitude of settings, e.g. the output type of the requested data and the definition of the extraction scope along each dimension. With this in mind, we prepare the payload within a notebook in Databricks and perform the API call. The connector returns the data according to the configuration of the payload. We extract the data from the response object and use PySpark to cast and write the data into a staging table.
Configuration and Selection
The payload must contain selection definitions for each dimension. There are four types of selections, which can be concatenated for a combined selection of values:
| Selection Type | Description |
| Specific Node | Extracts data for a single member only. |
| Leaf Nodes | Extracts only the base-level children. |
| Descendants | Extracts the node and all downstream members. |
| [None] | Aggregates all nodes along the dimension. |
Further options include the selection of the return format. We use either the CSV or JSON format, depending on the specifics of the returned data, to minimize data volume and thus network traffic.
Exports of additional Information
Alongside the financial statements, additional information can be extracted from HFM. Examples include currency exchange rates and metadata.
Currency conversions
In a globalized world, organizations operate in many countries and process payments in different currencies; therefore, conversion rates between currencies are crucial for unified reporting. Like financial statements, conversion rates can be extracted from Hyperion Financial Management.
Get to know the Dimensions
Extracting all descendants of a node yields many individual records. As the hierarchical information is not part of the financial statements, interpreting them without it is difficult. In addition to the financial information, we therefore extract the list of members with their corresponding attributes as well as entire hierarchies. This enables in-depth analyses of finances throughout the organizational structures.
Stay with the relevant data
Furthermore, the information contained within Hyperion Financial Management is vast, and data from older periods is static. We established time windows, fixed relative to the current active period, to retrieve relevant data. These time windows may select current financial statements, but also forecasted values or assigned budgets. They automatically shift each quarter without additional input, while maintaining the ability to manually trigger the extraction for a specific date.
Ingestion into Azure Databricks
Our framework features a medallion-based architecture, recommended by Databricks as best practice.
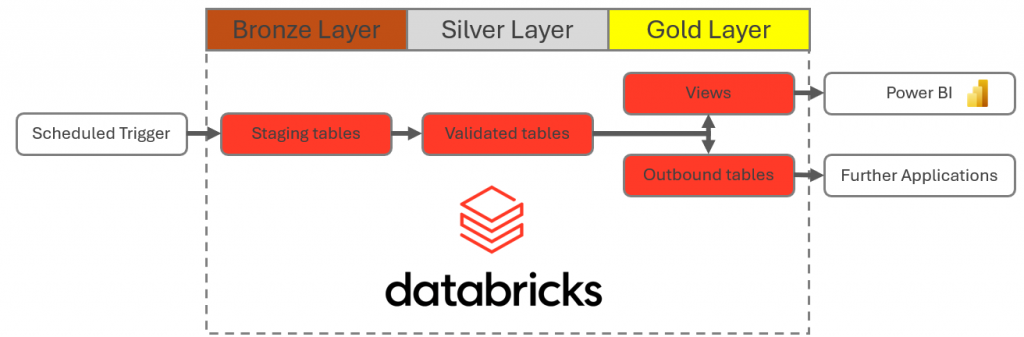
- bronze for basic format validations
- silver for more complex validations and derivations
- gold for end-user reporting as well as deliveries to other systems
From the response of the API request, we extract the content, use PySpark to cast each column to the correct data type and write it to the bronze tables. During the load from the bronze to the silver layer, we perform validations, transformations and derivations based on customizable building blocks.
By joining the HFM security classes with metadata tables in the silver layer, we dynamically derive security roles. In the gold layer, data is aggregated for reporting and security classes are mapped to actual roles. Combined with Databricks Unity Catalog, this enables Row-Level Security (RLS). This ensures that a user from the French branch only sees French data, even if the underlying table contains the entire global dataset.
Conclusions
By automating the bridge from HFM to Azure Databricks, we have moved beyond manual Excel exports to a modern, secure, and „live“ data landscape. With the financial statements, as well as currency conversion rates and metadata information on dimensions available via Databricks Unity Catalog, the organization is now equipped to build state-of-the-art reporting applications and make data-driven decisions with confidence.